

Local Projections: How to Estimate Impulse Responses
Learn how local projections estimate impulse responses at each horizon, how to read confidence intervals, and why identification and model choices still matter.
In this guideAn impulse response traces what follows a shock
Short summary
A local projection (LP) estimates the response at each future horizon with a separate regression. The resulting coefficients form an impulse-response path, but the regression alone does not show that a shock is causal. Identification, controls, and the uncertainty calculation still determine what the path means.
An impulse response traces what follows a shock
An impulse-response function (IRF) describes how an outcome evolves after a defined change or shock. A researcher might ask how output responds to an unexpected interest-rate increase, how a security responds to a dated announcement, or how a portfolio responds to an identified risk shock. The path across horizons can show when an effect appears, when it is largest, and how long it persists.
The word “shock” needs a definition. An observed movement in a policy rate, market price, or trading signal is not automatically an unexpected structural shock. It may partly reflect information about the outcome itself. Without a credible identification strategy, an LP coefficient is a conditional association or linear projection, not a causal response.
Each horizon gets its own regression
Let \(y_t\) be the outcome and \(s_t\) the shock measure. One common LP specification for horizon \(h\) is
\[ y_{t+h} = \alpha_h + \beta_h s_t + \sum_{j=1}^{p}\Gamma_{h,j}'W_{t-j} + \varepsilon_{t,h}. \]
Here \(h\) is the number of periods after the shock, \(W_{t-j}\) contains chosen lagged controls, and \(\beta_h\) is the coefficient of interest. The researcher estimates a different regression for \(h=0,1,2,\ldots\). Plotting the \(\hat\beta_h\) estimates against \(h\) gives the response path. With a structural shock and suitable identification, that path can estimate a structural IRF; otherwise, it describes a conditional predictive projection.
This direct estimation is the defining idea in Jordà’s original method: estimate the regression for each period of interest rather than repeatedly forecasting farther ahead from one fitted dynamic system. The separate estimates can be flexible, but they do not automatically share the smooth dynamics imposed by a single system.
At the observation level, each row links a shock date \(t\) to an outcome date \(t+h\). At \(h=0\), the outcome is measured in the shock period; at \(h=6\), it is measured six periods later. The shock dates stay fixed while the dependent variable shifts, so larger horizons can remove rows near the end of the sample. Use a consistent shock definition and comparable controls across horizon-specific regressions if the coefficients are to be read together as one path.
Define the outcome, shock, and units before fitting
The coefficient \(\beta_h\) is only interpretable after the variables and their scale are stated. If \(s_t=1\) represents a 25-basis-point unexpected policy-rate increase, then \(\beta_h\) is the estimated response to that size of shock. If \(s_t\) is measured in percentage points, the coefficient instead gives a response per percentage point. Rescaling the shock rescales every coefficient.
The dependent variable also determines whether the path is cumulative or period-by-period. For example, if \(Y_t\) is a positive output index, define
\[ r_{t,h} = 100\,[\log(Y_{t+h})-\log(Y_{t-1})]. \]
Then \(r_{t,h}\) is the approximate percentage change in the index from the pre-shock level through horizon \(h\). A different outcome, such as the monthly change in output, answers a different question. Do not describe a cumulative level response as the change occurring only in month \(h\).
Multiplying a log difference by 100 gives an approximate percentage change for small movements. With cumulative log output as the dependent variable, \(\beta_h\) measures the estimated difference between the pre-shock baseline and the level \(h\) periods later. A monthly growth rate as the outcome instead estimates a period-specific growth response. Label whether a result is a level, cumulative, or period-by-period change; a chart that only says “output response” can hide that distinction.
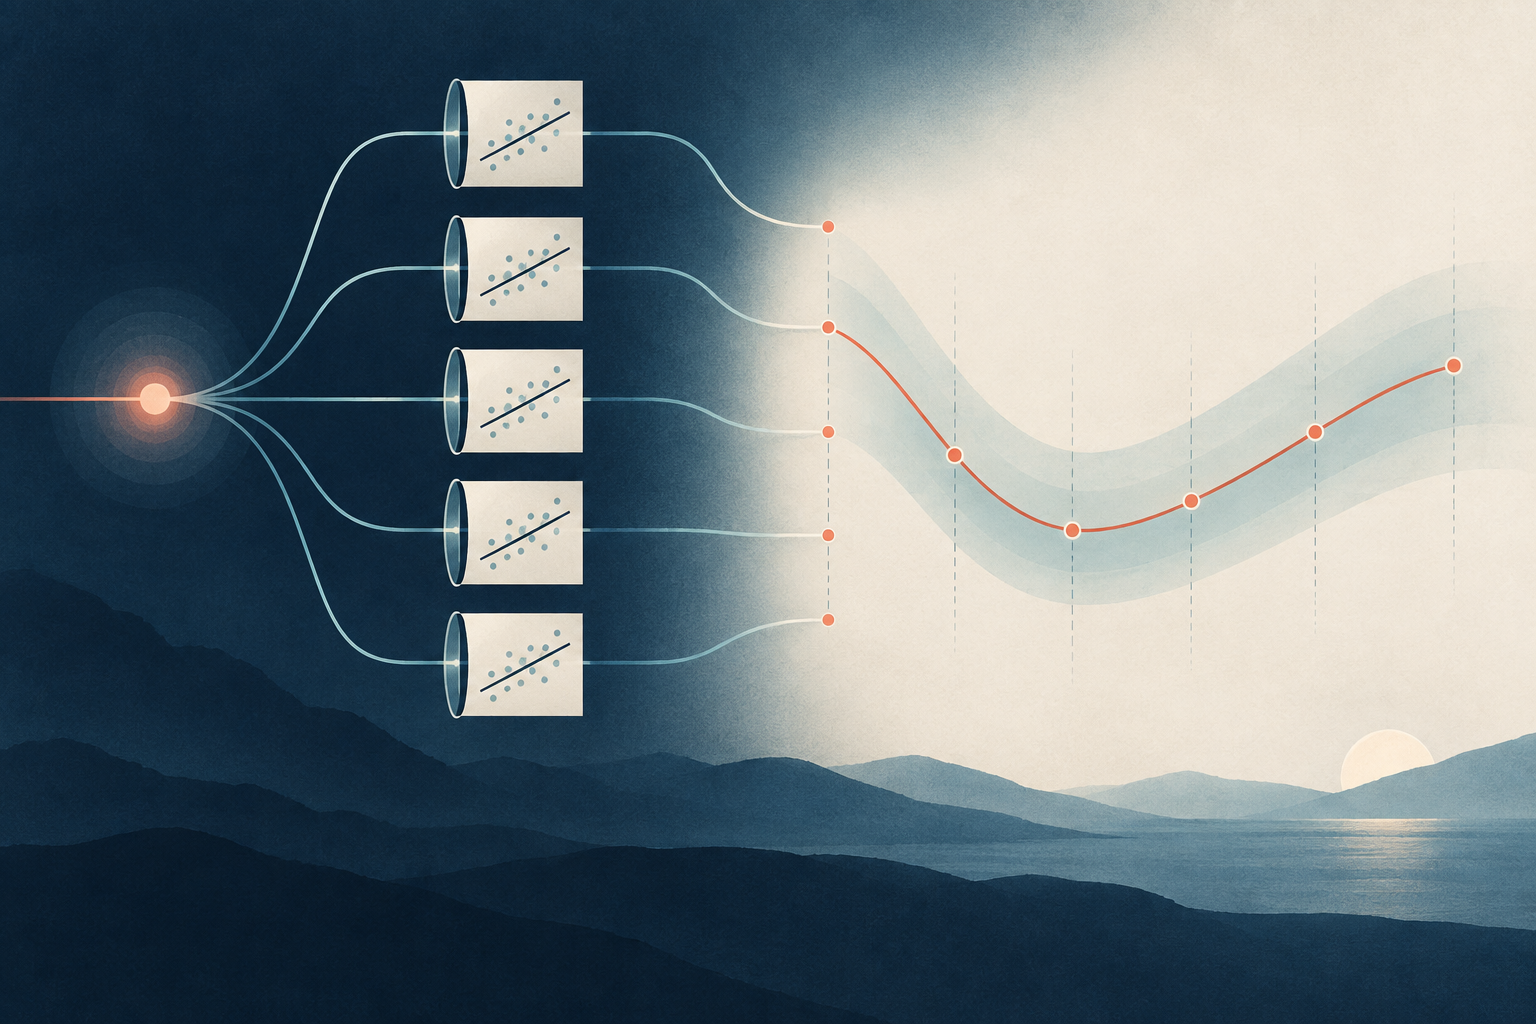
A hypothetical rate-shock example shows how to read the path
Suppose a monthly study defines \(s_t=1\) as a 25-basis-point unexpected rate increase and uses the cumulative output measure above. The following numbers are hypothetical teaching values, not estimates from real data. The intervals use \(1.96\) times each listed standard error only to illustrate pointwise arithmetic.
| Horizon | Estimated response | Standard error | Pointwise 95% interval |
|---|---|---|---|
| 0 months | 0.00% | 0.050 | [−0.10%, 0.10%] |
| 1 month | −0.10% | 0.061 | [−0.22%, 0.02%] |
| 3 months | −0.35% | 0.117 | [−0.58%, −0.12%] |
| 6 months | −0.60% | 0.163 | [−0.92%, −0.28%] |
| 12 months | −0.25% | 0.230 | [−0.70%, 0.20%] |
In this example, the six-month estimate is 0.60% below the pre-shock level, and its pointwise interval excludes zero. The twelve-month estimate is less negative, but its interval includes zero. That does not by itself prove a recovery between months six and twelve: the estimates are uncertain and correlated across horizons, and overlapping intervals do not test the difference between two horizons. A claim about the path needs an appropriate contrast or joint inference. None of these numbers is a policy forecast or a result about an actual economy.
The six-month value does not mean that output fell by 0.60% during month six alone. Under the stated cumulative outcome, it is an estimated level difference from the pre-shock baseline. Nor does a twelve-month interval that includes zero prove that the effect has disappeared; it says zero is not excluded by that pointwise calculation and standard error. An interval describes estimation precision. It does not remove limits in the sample or shock identification.
Identification and controls give the coefficient its meaning
LP is an estimation method; it does not supply the identifying variation. A researcher may define a shock from a structural model, a high-frequency surprise measure, a valid external instrument, or a research design with defensible assumptions. Each approach requires evidence that separates the shock from other news and from feedback in the outcome.
Controls should reflect the timing of the question. Lagged, pre-shock variables can account for earlier conditions. A variable measured after the shock may itself respond to the shock. Controlling for such a mediator can remove part of the total response or introduce new bias. Write down the information available just before the shock and explain why each control belongs in the regression.
A significant \(\hat\beta_h\) does not turn an unanticipated-looking event into an exogenous shock. Check anticipation, simultaneous announcements, measurement error, changing policy rules, and sample selection. In finance, overlapping news or common shocks can make outcomes move together even when the event of interest is not the cause.
With an external instrument, explain why it is related to the shock of interest and why it has no other path to the outcome under the exclusion restriction. A high-frequency surprise measure also needs checks on what news falls inside the announcement window and how quickly prices incorporate information. Set out the identification argument first, then choose an LP to estimate the response to that shock. A good fit or a small p-value does not establish the identifying assumptions.
Local projections and VARs share a population target under common conditions
LPs and vector autoregressions (VARs) are often introduced as competing ways to estimate IRFs. Plagborg-Møller and Wolf show that, with matching information and identification, compatible shock normalization, and unrestricted lag structures, the two approaches can estimate the same population response. The result is about a common estimand; it does not say that finite-sample estimates must match or that every fitted LP and VAR uses the same restrictions.
With a fixed number \(p\) of lags, their response estimands can approximately agree through horizons \(h\leq p\), while differences may emerge at longer horizons. In finite samples, LPs estimate each horizon directly and may be more variable, while a VAR uses a joint dynamic model that can make the path more regular. That structure can help when it is suitable and can mislead when its restrictions are poor. There is no universal winner based only on the method’s name.
Rather than memorizing “LPs are more robust and VARs are more efficient,” check which dynamic restrictions each specification uses. Even if flexible specifications share a population target, estimates and precision can differ when the sample, lag count, and information set differ. Shock normalization also needs to match before coefficient magnitudes are compared. Record the shock scale, included variables, lag length, sample, and identification restrictions for each method.
Confidence intervals depend on the horizon and inferential method
For each \(h\), the regression produces an estimate and uncertainty measure. As \(h\) grows, fewer observations may remain because the outcome \(y_{t+h}\) is unavailable near the sample end. Multi-step outcomes also overlap, so residuals and estimates across horizons can be dependent. The chosen standard error or bootstrap must match the design and the inferential target.
A pointwise 95% interval is constructed for one horizon at a time. It does not guarantee 95% coverage of the full response curve. A simultaneous confidence band is a different object and should be reported when a claim concerns the path as a whole. Montiel Olea and Plagborg-Møller establish useful results for particular lag-augmented LPs under their assumptions; those results are not permission to omit diagnostics or copy a standard-error recipe into any regression. In their unit-root setting, the stated results do not cover horizons that grow in proportion to the sample size. State the controls, horizon range, covariance or bootstrap method, and whether the intervals are pointwise or simultaneous.
Multi-step outcomes overlap, so regression residuals may be serially correlated. That does not mean that choosing the same HAC bandwidth for every LP is always adequate. The lag-augmented result in the inference paper relies on a particular regression setup, including lagged values of the system variables, and on its stated conditions. In an application, explain how the standard-error method fits the estimator, persistence of the series, sample length, and horizons of interest. Wider intervals at long horizons can reflect fewer observations and less information, rather than a calculation error.
Flexible responses add questions and estimation choices
Researchers can interact the shock with an observed state, such as a recession indicator, to ask whether responses differ across regimes. They can also study several outcomes, shock sizes, or subsamples. Each extension changes the estimand and uses the available observations differently; dividing the sample may leave wide uncertainty, especially at long horizons.
Pre-specify which horizons and states matter when practical. If many outcomes, lags, samples, or shock definitions are tried, report the search rather than presenting the selected path as if it were the only analysis. Smoothing across horizons can make a plot easier to read, but it adds restrictions or tuning choices; show the unsmoothed estimates and document the method if a smoothed curve is also shown.
Report enough detail to reproduce the response path
State the outcome, frequency, transformation, shock definition and units, horizon range, sample dates, control set, and treatment of missing observations. Explain the identification assumptions separately from the regression formula. Report the coefficient and uncertainty at each horizon or show a figure with legible units and interval definitions.
Name the estimation and inference procedure, including lag length, covariance estimator or bootstrap, and whether intervals are pointwise or simultaneous. Show relevant sensitivity to a defensible alternative shock measure, lag choice, or sample window. An IRF is a model-based summary of a particular identified shock and outcome; it is not a trading signal or a guarantee of future returns.
Jordà’s original local-projection paper introduces horizon-by-horizon estimation. Plagborg-Møller and Wolf’s LP–VAR equivalence result clarifies the shared population target and finite-lag distinction. Montiel Olea and Plagborg-Møller’s inference analysis studies lag-augmented LP confidence intervals under specified conditions. Related guides cover financial event studies, robust and HAC standard errors, and difference-in-differences event-time designs.
Common questions
Q1Is a local projection automatically causal?
No. It estimates horizon-specific relationships. A causal IRF requires a defensible strategy for identifying the shock and the assumptions behind that strategy.
Q2Do local projections always outperform VARs?
No. Under common population conditions they can target the same response, while finite-sample behavior depends on lag length, restrictions, sample size, and the data. Neither method dominates in every application.
Q3Are pointwise confidence intervals enough for an impulse-response plot?
They are enough only for statements about each horizon separately. If the claim is about the whole curve, use and report a suitable simultaneous band.
Sources and further reading
Report an issue
We’ll prepare an email with this article link. Mark receives the report only after you send it
Quick check
Read the guide? Check yourself with 3 questions
Question 01
What makes a regression a local projection?
Choose an answer to see the explanation
Options glossary
Variation in the conditional error variance across regressor values or states, invalidating an equal-variance covariance formula.
Read the deeper guideDifference-in-differencesA quasi-experimental method subtracting the comparison group's contemporaneous change from the treated group's change to construct an untreated counterfactual.
Read the deeper guide