

Lee–Mykland Jump Test: Detecting Intraday Price Jumps
Learn how the Lee–Mykland test scales each intraday return by recent bipower variation, calibrates a session-wide jump threshold, and handles sampling and market-noise limits.
In this guideIdentify an interval, not just a volatile day
Short summary
The Lee–Mykland procedure asks whether an individual high-frequency return is unusually large relative to a recent local-volatility estimate. It uses a bipower-variation scale built from earlier returns and a threshold calibrated for the largest statistic across a testing period. A flagged interval is evidence against a continuous-path null under the method’s assumptions; it is not proof of a news cause, a forecast, or a trading signal.
Identify an interval, not just a volatile day
Realized variance adds squared intraday returns across a session. Bipower variation can estimate the continuous component of variation under specific jump and sampling assumptions. Both summarize a period, so neither by itself says when an unusually large move occurred. Lee and Mykland’s method instead evaluates returns interval by interval, comparing each candidate move with volatility estimated from the returns just before it.
The distinction is useful for event studies, volatility modeling, and describing jump timing. A 1% return may be extraordinary in a quiet market and ordinary during a volatile session. Standardizing by recent local volatility accounts for that changing scale. The procedure was introduced to detect intraday jump arrivals and estimate their realized sizes; it does not establish why a move occurred or whether it was tradable (Lee & Mykland, 2008).
The null is about the price process over a particular interval: no jump occurred there, under a continuous component with regularity conditions. It is not the claim that the return is zero. Continuous price paths can still produce large returns, especially when volatility is high, which is why a size-only cutoff is inadequate.
Build the return series used by the test
Let \(P_i\) be the price observed on a regular grid at time \(t_i\). Define the log return over interval \(i\) as
\[ r_i=\log(P_i/P_{i-1}). \]
The test relies on a consistent price field and grid. A researcher might use transaction prices, quote midpoints, or another documented proxy, but changing the proxy can change both the return and the jump label. Session openings, closures, auctions, trading halts, and missing quotes need explicit treatment. A close-to-open return should not be silently mixed with ordinary intraday intervals.
Regular sampling matters because the local scale and extreme-value threshold are derived for a specified observation scheme. If observations are irregular, first choose a defensible synchronization or sampling rule and explain what information it discards. The formula does not make stale quotes, crossed markets, bad timestamps, or isolated recording errors disappear. Nor should prices from different venues or assets be combined as though they were synchronous without checking alignment.
This is a test on observed returns, not latent prices. The original theory uses high-frequency semimartingale models with conditions that do not automatically hold for every quote feed or digital-asset venue. Record the source, time zone, grid, trading session, and any filters so another analyst can reconstruct the series.
Estimate volatility from the preceding window
At candidate time \(t_i\), estimate the local variance from returns before \(r_i\):
\[ \widehat{\sigma}_i^2 = \frac{1}{K-2} \sum_{j=i-K+2}^{i-1}|r_j|\,|r_{j-1}|, \qquad \widehat{\sigma}_i=\sqrt{\widehat{\sigma}_i^2}. \]
Here \(K\) controls the rolling window. The sum contains products of adjacent absolute returns; the candidate return \(r_i\) is left out. This bipower-variation form helps keep an earlier isolated jump from dominating the scale used to judge a later interval. The broader realized-volatility literature explains why sums and products of high-frequency returns can estimate different features of quadratic variation (Barndorff-Nielsen & Shephard, 2002).
The estimate is local, not a full-session volatility forecast. A short window adapts quickly but can be unstable, while a long window is smoother but can lag a volatility change. The original asymptotic argument chooses \(K\) to grow as the sampling interval shrinks while remaining short relative to the full horizon. A practical finite sample needs a documented choice and sensitivity analysis; there is no universal \(K\) that fixes every asset, grid, or market regime.
A zero or nearly zero estimate also needs a policy. Dividing by a tiny scale can create an extreme statistic from a small price tick. Do not silently replace such values with an arbitrary floor: report the rule, check the underlying quotes, and show whether reasonable alternatives change the flagged intervals.
Standardize each candidate interval
The local jump statistic is
\[ L_i=\frac{r_i}{\widehat{\sigma}_i}. \]
Its sign retains the direction of the observed return, while its magnitude measures the move relative to the preceding local scale. The estimate in the denominator uses adjacent absolute-return products without the conventional bipower normalization constant. Under the paper’s no-jump asymptotics, \(L_i\) is approximately \(Z_i/c\), where \(Z_i\) is standard normal and \(c=E|Z_i|=\sqrt{2/\pi}\). This detail matters when calibrating the threshold: treating \(L_i\) as a standard normal statistic gives the wrong reference distribution.
A large \(|L_i|\) marks a candidate interval, not an automatic finding. The test asks whether the move is unusually large after accounting for the sampling scheme, window, and number of intervals being searched. A positive statistic identifies an upward observed return; a negative one identifies a downward return. Neither sign identifies an economic cause, and the sign alone does not distinguish a jump from a continuous move or data error.
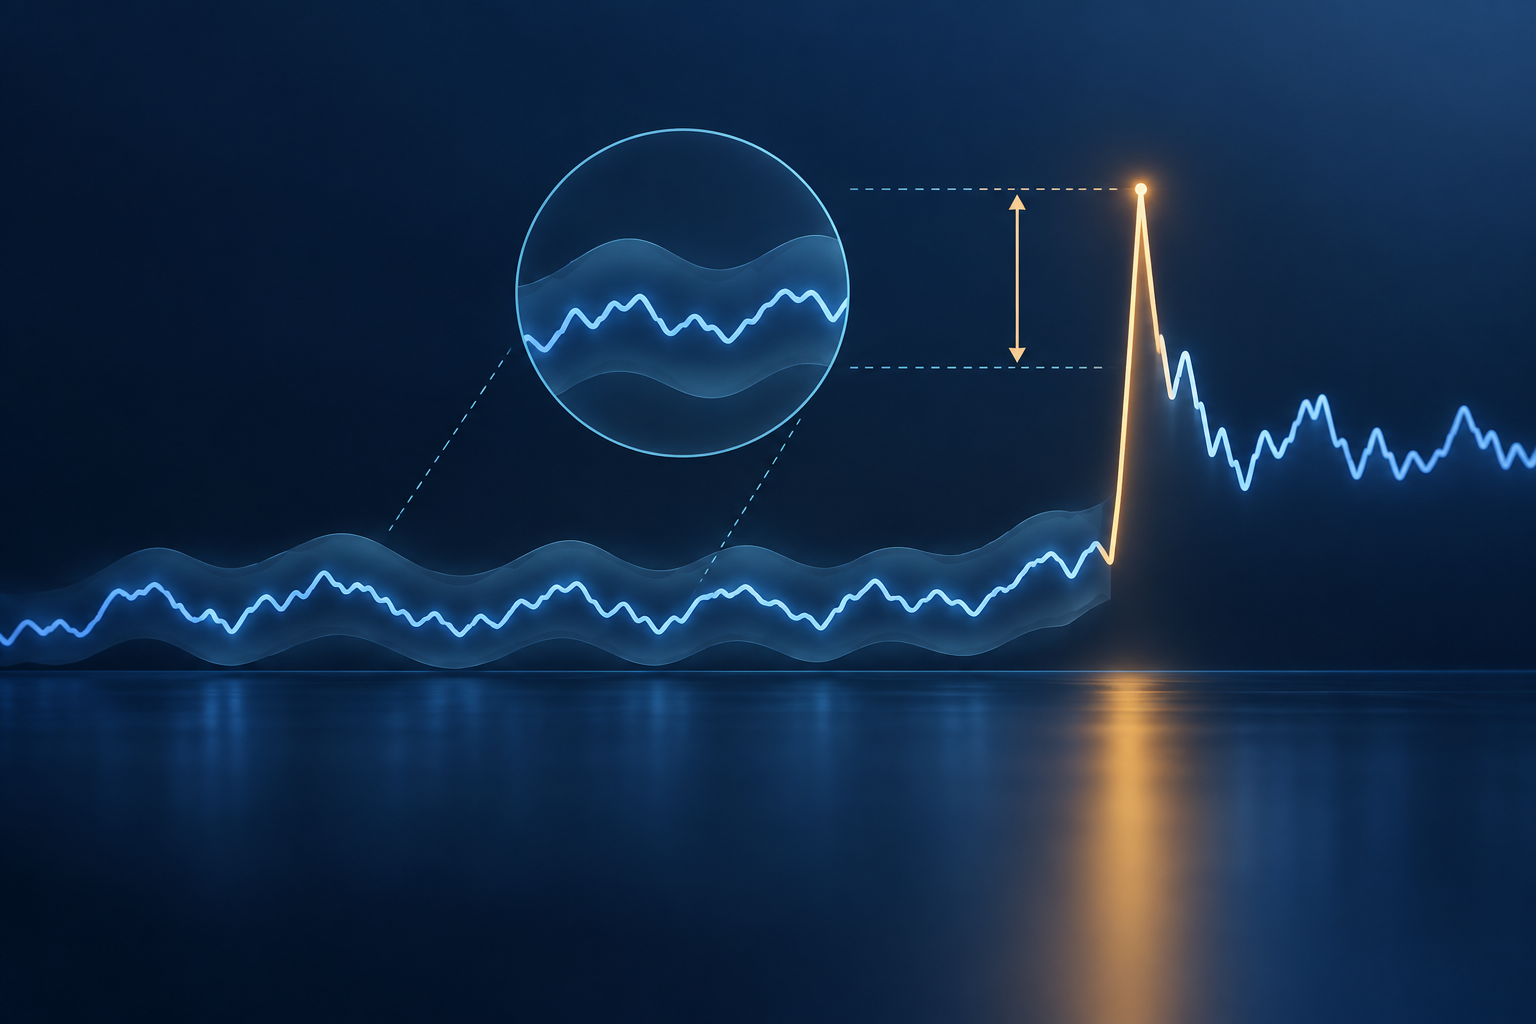
The figure below shows one candidate return compared with a local scale estimated from earlier intervals. It is conceptual rather than a price chart or a detected event.
<!-- learn:illustration --> <!-- Text-free concept: one sharp return pulse rises above a quiet sequence while a trailing window forms a soft local-volatility envelope; no prices, timestamps, thresholds, or detected events are shown. -->
Set a threshold for the full testing period
When scanning \(n\) intervals, a pointwise threshold applied \(n\) times can produce false alarms simply because many observations were checked. Lee and Mykland calibrate the maximum absolute statistic over the horizon. With \(c=\sqrt{2/\pi}\), define
\[ C_n= \frac{\sqrt{2\log n}}{c} - \frac{\log(\pi)+\log(\log n)} {2c\sqrt{2\log n}}, \qquad S_n=\frac{1}{c\sqrt{2\log n}}. \]
Under the paper’s asymptotic no-jump conditions,
\[ \frac{\max_{1\le i\le n}|L_i|-C_n}{S_n} \]
has a standard Gumbel limiting distribution with cumulative distribution function \(F(x)=\exp(-e^{-x})\). For session-level significance \(\alpha\), the corresponding critical value is
\[ \beta_\alpha=-\log[-\log(1-\alpha)]. \]
An interval is flagged when \((|L_i|-C_n)/S_n>\beta_\alpha\). The maximum calibration addresses the search across intervals in that stated horizon. It does not automatically correct a study that repeats the scan across many assets, days, sampling grids, or model variants. Those additional comparisons need their own design and disclosure.
Work through a hypothetical interval
Suppose the three returns immediately before a candidate interval are \(-0.40\%\), \(+0.30\%\), and \(-0.20\%\), and set \(K=4\) only to make the arithmetic short. Then
\[ \widehat{\sigma}_i^2 = \frac{|0.30||-0.40|+|-0.20||0.30|}{2} = 0.09\;(\%)^2, \qquad \widehat{\sigma}_i=0.30\%. \]
If the next return is \(+1.20\%\), its local statistic is \(L_i=1.20/0.30=4\). That says the observed return is four times this illustrative local scale; it does not yet say that the test rejects.
For an illustrative session with \(n=78\) intervals, the asymptotic formulas give \(C_n\approx3.14\) and \(S_n\approx0.424\). At a 1% session-level significance level, \(\beta_\alpha\approx4.60\), producing a threshold near \(3.14+0.424(4.60)=5.10\). The statistic 4 is below that threshold, so this example would not flag the interval at that level. The values are hypothetical, and the maximum approximation may be rough at this sample size. The small \(K=4\) window illustrates the calculation only; it is not a recommended estimator setting.
This example shows why “four standard deviations” is not a complete description of a Lee–Mykland decision. The reference scale, asymptotic normalization, window, number of intervals, and significance level all affect the cutoff. State them alongside any jump count or event list.
Choose the sampling grid and window together
A finer grid improves time resolution in theory, but it also exposes more quote noise, price discreteness, and timestamp mismatch. A coarser grid smooths some short-lived variation but can combine a jump with neighboring continuous returns or hide multiple moves inside one interval. The selected grid therefore changes both what the test can detect and how well its assumptions fit the observations.
The window \(K\) is coupled to that grid. Too few preceding returns make the local bipower estimate erratic; too many can mix different volatility regimes and dilute the meaning of “local.” Report \(K\) in both observations and clock time, explain whether windows reset at session boundaries, and show how the event list changes under defensible alternatives. Do not import a window recommendation from a different market, session length, or observation frequency without checking it.
The standard Lee–Mykland setup is not a general solution to market microstructure noise. Pre-averaging and other noise-aware procedures alter the return or volatility estimates and require matching inference; they are not interchangeable drop-in filters (Aït-Sahalia, Jacod & Li, 2012). The pre-averaging guide and two-scale volatility guide explain two related responses to noisy high-frequency prices.
Interpret a detected interval as a research label
A flagged return is evidence that the observation is difficult to reconcile with the model’s continuous-path null at the stated threshold. It is not confirmation of a scheduled announcement, an exchange failure, a liquidation cascade, or any other cause. Compare the timestamp with verified event data, inspect the underlying trades and quotes, and check whether the movement persists after the interval. Keep those follow-up explanations separate from the statistical test.
The procedure is also distinct from an end-of-day comparison of realized variance and bipower variation. The Lee–Mykland statistic is designed to locate intervals relative to local volatility; a daily variation gap estimates aggregate jump variation under different assumptions. The bipower-variation guide and realized-volatility guide cover those period-level measures. Aït-Sahalia and Jacod’s power-variation test asks whether jumps are present in a discretely observed path using a different construction. Its target and assumptions differ, so agreement or disagreement with an interval-level Lee–Mykland list is not a one-for-one validation.
For a strategy, a jump label is an input for later research, not a buy or sell instruction. A backtest must account for when the signal becomes observable, spread and slippage, latency, overlapping event windows, and out-of-sample evaluation. Use a stated loss or risk objective and compare against a suitable benchmark. A statistically flagged historical return does not show that a future event can be predicted or traded profitably.
Common questions
Q1Is every large intraday return a jump?
No. A large return can arise from a continuous price path during high volatility, a jump, noise, a bad quote, or a timestamp problem. The test compares the move with a local volatility estimate and its assumptions.
Q2Does the Lee–Mykland test use bipower variation?
Yes. It uses a rolling local scale based on products of adjacent absolute returns before the candidate interval. This differs from using a full-session realized variance minus bipower variation.
Q3Does a 1% threshold mean each interval has a 1% false-alarm chance?
No. The threshold is calibrated from the maximum over the stated testing horizon under asymptotic assumptions. Repeating the scan across many assets, days, or parameter choices creates further comparisons.
Q4Can the test be applied to tick data without adjustment?
Not automatically. Price discreteness, bid–ask bounce, stale quotes, and timing errors can distort returns and the local scale. Noise-aware methods change the estimation and inference and need their own calibration.
Sources and further reading
Report an issue
We’ll prepare an email with this article link. Mark receives the report only after you send it
Quick check
Read the guide? Check yourself with 3 questions
Question 01
What does the Lee–Mykland denominator estimate?
Choose an answer to see the explanation